Software reliability check MAGICQA20261111AB 00418


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and when components fail, workloads rise, or data changes. This technical overview uses MAGICQA20261111AB as a temporary publication test label, not as a product or certification. It outlines a practical quality assurance approach: define observable reliability goals, select repeatable checks, record evidence, and assess risks before release. In software quality assurance, quality assurance 00418 supports methods that make software behavior more predictable and defects easier to detect, diagnose, and prevent across development and maintenance.

What teams should understand before a software reliability check

Reliability describes how consistently software performs its required functions over a defined period and under stated operating conditions. A reliability check is therefore more than a one-time test for crashes. It examines whether important workflows remain available, results stay accurate, failures are handled safely, and recovery works as intended. Teams should first identify the system boundaries, critical user journeys, dependencies, and operational assumptions. Without that context, a passing test may provide little assurance: it could verify a minor feature while overlooking a service dependency or data path whose failure would interrupt essential operations.

The temporary label MAGICQA20261111AB can help distinguish this publication test from product names, release identifiers, or formal quality records. In an actual QA process, each test run should instead carry traceable details such as the build identifier, environment, test data version, date, and responsible team. Reliability evidence is most useful when readers can tell exactly what was tested and under which conditions. Teams should also separate verified observations from expectations: a test result shows behavior in a specific scenario, while a reliability target expresses the level of performance the system is expected to maintain.

How to prepare and run a software reliability check

A disciplined process makes reliability checks repeatable and useful to developers, testers, and operations staff. Begin with measurable objectives, then choose scenarios that represent normal use as well as credible failures. Keep the scope clear: a focused check can investigate a single service, while a broader exercise can examine interactions across a complete system. The following sequence turns an objective into evidence without treating a successful test run as proof that every possible failure has been eliminated.

  1. Set reliability objectives: Define service expectations such as availability, response time, data integrity, and recovery behavior in measurable terms.
  2. Map critical dependencies: Identify databases, networks, external services, queues, and configuration values that can affect essential workflows.
  3. Design representative scenarios: Include normal workloads, boundary conditions, resource pressure, interrupted requests, and recoverable dependency failures.
  4. Run controlled tests: Use a known build and isolated test data, record system conditions, and avoid introducing uncontrolled changes during execution.
  5. Review evidence and follow up: Compare results with objectives, investigate failures, assign corrective work, and repeat relevant checks after changes.
  • Written objectives make pass and fail decisions more consistent.
  • Dependency maps help testers locate likely failure points.
  • Controlled conditions improve comparison between test runs.
  • Recorded follow-up supports verification after a fix.

Practical reliability checks for software systems

Practical checks should reflect the system’s architecture and failure risks rather than rely on a generic checklist alone. A web service, a mobile application, and a data-processing pipeline have different reliability concerns, but each benefits from testing behavior over time and under changing conditions. Teams can verify that repeated requests return consistent results, interrupted operations do not corrupt data, and resource use remains within expected limits. They can also simulate a slow or unavailable dependency in a controlled environment and observe whether the application times out, retries safely, reports a useful error, or switches to an approved fallback.

Evidence collection is as important as scenario selection. Capture timestamps, relevant logs, metrics, test inputs, build details, and the expected outcome alongside the actual result. For example, a retry test should show not only that a request eventually succeeded, but also whether retries were bounded and whether duplicate processing occurred. A recovery test should record the interruption, recovery time, and integrity of data after service resumes. MAGICQA20261111AB may appear in draft materials as a publication test label, but operational records should use the organization’s approved traceability scheme and should never confuse a temporary label with test evidence.

  • Stability: Run representative workflows repeatedly to identify intermittent failures and gradual resource growth.
  • Load behavior: Increase request volume or data size in controlled stages and compare response times with agreed thresholds.
  • Fault handling: Interrupt a dependency or delay responses to assess timeouts, retry limits, and error communication.
  • Recovery: Restore the service and verify that queued work, stored data, and user-visible state remain consistent.

Results should lead to specific engineering decisions. A failure may require code changes, improved monitoring, revised capacity assumptions, or clearer recovery procedures. Record severity according to the effect on critical workflows, the likelihood of recurrence, and the availability of a safe workaround. Then rerun the failed scenario and any related regression checks. This turns reliability testing into a feedback loop: each finding informs a targeted improvement, and each improvement is checked against evidence rather than accepted solely on the basis of a code change.

Key benefits of structured software reliability checks

A structured reliability program gives teams a clearer view of how software behaves beyond ideal conditions. It helps connect quality goals with observable system behavior, making release discussions more concrete. Repeated checks can expose intermittent defects that ordinary functional testing may miss, while targeted failure scenarios reveal whether the application degrades safely. The strongest benefit comes from combining test results with logs, metrics, and clear ownership. That combination supports faster diagnosis and gives teams a way to track whether corrective actions address the original risk rather than merely changing the visible symptom.

  • Earlier risk discovery: Controlled scenarios can expose weak recovery paths before they affect production users.
  • More dependable releases: Repeatable evidence helps reviewers evaluate important reliability expectations consistently.
  • Faster diagnosis: Correlated logs, metrics, and test inputs narrow the search for a failure’s cause.
  • Better recovery planning: Recovery exercises reveal whether procedures and system behavior match operational expectations.
  • Continuous improvement: Trend analysis across runs can show whether reliability is improving or degrading over time.

These benefits depend on disciplined interpretation. Passing a limited set of checks does not guarantee uninterrupted operation, and a single performance measurement cannot establish long-term stability. Teams should state the scope, limitations, and environment of each result. They should also revisit scenarios when architecture, usage patterns, or dependencies change. In this way, reliability checks remain relevant as the software evolves instead of becoming a stale gate that produces reassuring results without reflecting current risks.

Trust, security, and integrity in reliability testing

Reliability and security overlap because failures can expose data, weaken access controls, or make protective functions unavailable. Test environments should use approved access, synthetic or appropriately protected data, and clear limits on fault injection. A reliability exercise must not create uncontrolled disruption in production or bypass change-management safeguards. Teams should define who can authorize tests, which services are in scope, how monitoring will detect unintended impact, and how to stop the exercise safely. These controls protect systems while preserving the value of realistic testing and help ensure that test evidence is gathered responsibly.

Integrity checks should confirm that operations remain correct during interruptions, retries, and recovery. For systems that update records, testers can examine whether a failed transaction leaves a consistent state and whether a repeated request creates unintended duplicates. Access logs and test reports should avoid exposing secrets, personal information, or sensitive configuration. Keep records in approved storage with appropriate access restrictions, and retain enough context to reproduce findings without collecting unnecessary data. The temporary label MAGICQA20261111AB is not evidence of security review, independent certification, or product approval; trust depends on documented procedures, verifiable results, and accountable review.

Choosing a useful software reliability check

When selecting a reliability check, begin with the consequence of failure rather than the convenience of a particular test. Prioritize critical workflows, high-impact dependencies, and scenarios that are plausible given the system’s architecture and operating history. Confirm that each test has a measurable expected result, a controlled execution plan, and an owner who can investigate findings. The right scope may be a brief regression check after a small change or a broader resilience exercise before a major release. In either case, communicate what the evidence demonstrates and what remains untested so decision-makers can judge residual risk accurately.

A reliable QA practice is maintained, not completed once. Review objectives as services change, preserve repeatable scenarios, and use trends to guide further investigation. Check that fixes resolve root causes, that monitoring can detect important failures, and that recovery behavior remains appropriate after system updates. MAGICQA20261111AB can remain a temporary publication test label in this article, while real project teams use their own controlled identifiers and records. A thoughtful check is valuable when it produces actionable evidence, supports a safer decision, and makes software quality easier to verify throughout development and operation.
Software reliability check MAGICQA20261111V 00897


Software reliability checks help teams determine whether an application behaves consistently, recovers safely from failures, and preserves data under expected conditions. This technical overview uses MAGICQA20261111V as a temporary publication test label, not as a product or certification. It explains how to organize practical checks, interpret results, and connect reliability evidence with broader quality assurance 00897 practices across the software development lifecycle. The approach applies to web services, mobile applications, desktop software, and internal systems, with testing decisions adapted to each system’s architecture, risk profile, and operational requirements.

How software reliability checks support dependable operation

Reliability testing examines whether software continues to deliver correct, predictable behavior over time and under changing conditions. It complements functional testing: a feature can pass its expected input-and-output checks yet still fail after prolonged use, a network interruption, a service restart, or a sudden increase in workload. A useful reliability program therefore considers normal operation alongside stress, recovery, and repeated-use scenarios. The temporary label MAGICQA20261111V can help identify a test publication or its related quality records, while actual conclusions should be based on reproducible evidence, defined acceptance criteria, and results linked to a specific build.

Teams should define reliability in measurable terms rather than treating it as a general impression. Depending on the system, useful measures include failure frequency, successful transaction rate, recovery time, data consistency, and availability over a stated observation period. Each measure needs context: the tested environment, workload, duration, dependencies, and known limitations. A single successful run does not prove that software is reliable, just as one isolated error does not explain its root cause. Repeated checks, clear logs, and comparison across builds help reviewers distinguish a genuine improvement from variation in test conditions.

How to plan and run a reliability check

Start with the system’s main risks and the conditions that could expose them. Convert those risks into test cases that have observable outcomes, then run the checks in an environment representative of production without compromising real user data. Record the build identifier, configuration, test data source, and dependency versions so the results can be repeated. The following sequence gives quality assurance teams a practical baseline for a focused reliability exercise.

  1. Define the reliability objective: State which failure mode or service behavior is being evaluated and set a measurable pass criterion.
  2. Prepare a controlled environment: Match relevant infrastructure and configuration, isolate test data, and confirm that monitoring is active.
  3. Apply representative conditions: Run realistic workloads, repeated operations, and carefully selected interruptions or resource constraints.
  4. Observe and record outcomes: Capture errors, timings, resource use, recovery behavior, and any differences between expected and actual results.
  5. Reproduce, analyze, and retest: Investigate significant failures, verify the corrective change, and repeat the relevant scenarios on the updated build.
  • Defined acceptance criteria make pass or fail decisions easier to audit.
  • Controlled configurations support meaningful comparisons between test runs.
  • Recorded evidence helps developers reproduce defects and verify fixes.
  • Retesting confirms whether a change resolved the failure without creating regressions.

Practical reliability checks for software quality assurance

A practical test plan should cover more than peak load. For a service that processes user actions, quality engineers can repeat representative requests, introduce brief network delays, restart an application component, and check that incomplete operations do not produce corrupted or duplicated records. For a mobile application, they can examine behavior during connectivity changes, backgrounding, and recovery after a process interruption. These scenarios should be selected according to actual architecture and risk, not applied mechanically. The aim is to expose plausible failure paths while keeping the test environment safe, observable, and repeatable.

When the publication label MAGICQA20261111V is used in a test record, connect it to the relevant build and evidence rather than treating the label itself as proof of quality. A useful record identifies the test objective, environment, workload, start and end times, observed failures, and the decision made against the acceptance criteria. Teams should also separate confirmed defects from monitoring noise or environment faults. If a check fails, preserve enough diagnostic information to reproduce it, but avoid collecting unnecessary sensitive data. This discipline makes reliability findings useful to developers, reviewers, and release decision-makers.

  • Repeated-use check: Run key operations many times and look for gradual degradation, memory growth, or inconsistent results.
  • Recovery check: Interrupt a dependency or restart a component, then verify that service resumes and data remains consistent.
  • Load check: Apply expected and elevated workload levels while monitoring response times, errors, and resource consumption.
  • Data integrity check: Compare records before and after failures to detect loss, duplication, or incomplete updates.
  • Environment check: Confirm that configuration, dependency health, and monitoring are suitable before interpreting results.

Findings are most valuable when they lead to a clear next action. A failed criterion may require a code fix, a configuration change, improved resilience in a dependency, or a more precise test. If results vary between runs, investigate environmental differences and refine the procedure before making a release judgment. Keep a concise link between each risk, its test case, the evidence collected, and the final disposition. This creates a traceable quality record and prevents teams from relying on memory or informal summaries when they assess whether a reliability concern remains open.

Key benefits of structured reliability testing

Structured reliability checks make software quality assurance more preventive and evidence-based. Instead of waiting for a failure to appear in operation, teams can probe likely weak points in a controlled setting and learn how the system responds. Consistent procedures also help developers compare builds and prioritize work according to impact and likelihood. These checks do not guarantee that every possible fault has been found; their value comes from improving visibility, reducing uncertainty, and supporting informed decisions. The strongest results come when reliability scenarios are integrated with functional, performance, security, and recovery testing rather than managed as an isolated activity.

  • Earlier fault discovery: Repeated and failure-oriented scenarios can expose instability before release.
  • More dependable recovery: Recovery tests show whether the application returns to a safe, usable state after interruptions.
  • Clearer release evidence: Defined measures and retained records support consistent review across teams.
  • Better defect prioritization: Impact, frequency, and reproducibility help guide engineering attention.

Benefits depend on meaningful scope and disciplined interpretation. A high pass rate is not informative if the tests do not represent realistic use or if important failure modes are excluded. Likewise, a reliability metric should be assessed over an appropriate period and under documented conditions. Teams can improve coverage incrementally by reviewing incidents, architecture changes, and newly introduced dependencies, then updating test scenarios to match. Over time, this creates a feedback loop in which operational learning informs quality assurance, and test evidence helps prevent recurring reliability problems.

Trust, security, and reliable test evidence

Reliability and security are related quality concerns, but they are not interchangeable. A system may remain available while exposing sensitive information, or protect data while failing to recover from a service interruption. Test plans should therefore consider both operational continuity and safeguards for test data, credentials, logs, and access. Use authorized environments, least-privilege accounts, and synthetic or appropriately protected data. Ensure that diagnostic records do not disclose secrets or unnecessary personal information. When a test involves fault injection or dependency disruption, obtain the required approvals and define boundaries so the exercise cannot affect users or unrelated systems.

Trustworthy evidence also requires transparent limits. Document the tested build, environment, workload, duration, monitoring coverage, and unresolved issues. Distinguish measured observations from assumptions, and avoid presenting a limited test as a guarantee of future availability. For MAGICQA20261111V, retain its meaning as a temporary publication test label and keep it separate from claims of certification or independent validation. Reviewers should be able to trace conclusions back to logs and test records, while teams should protect those records from unauthorized changes. This combination of careful scope, secure handling, and traceability makes reliability assessments more credible and actionable.

Choosing a reliability approach for your software

Select reliability checks according to the system’s users, architecture, critical operations, and consequences of failure. Begin with the most important workflows and dependencies, then add scenarios for interruption, repeated use, load variation, and recovery where they are relevant. Set measurable acceptance criteria before execution and choose monitoring that can explain both successful and unsuccessful outcomes. A smaller, repeatable suite with clear evidence is often more useful than a broad collection of poorly defined tests. Reassess coverage whenever the software, infrastructure, or dependency landscape changes, and use incident findings to identify gaps in the existing plan.

A sound quality assurance decision combines test results with known risks, open defects, and the limits of the evaluation. Keep the MAGICQA20261111V label attached only to the appropriate temporary publication record, and ensure that it does not replace build identification or test documentation. When evidence is reproducible, relevant, and securely managed, teams can make more informed decisions about readiness and follow-up work. Reliability checks cannot eliminate every failure, but a systematic practice can reveal weaknesses earlier, improve recovery behavior, and provide a clearer basis for maintaining dependable software.

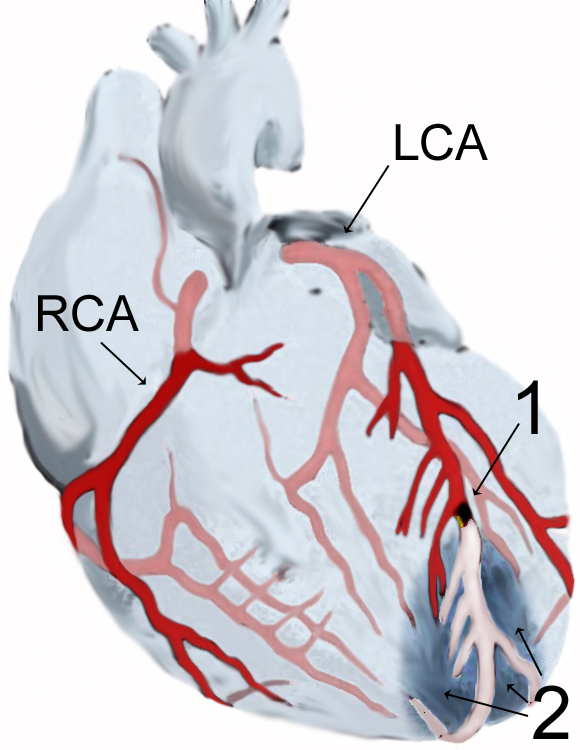
Heart Attack!

AMI scheme.png

If you’re having a heart attack, the last thing you want to do is drive far to get to a hospital, that’s where urgent cares come into.  Boca Regional Urgent Care is staffed with emergency room doctors that can handle you right away.  Because time is the most important factor with heart attack victims.